
 Upgrade Storage
the scraping reference process get stuck
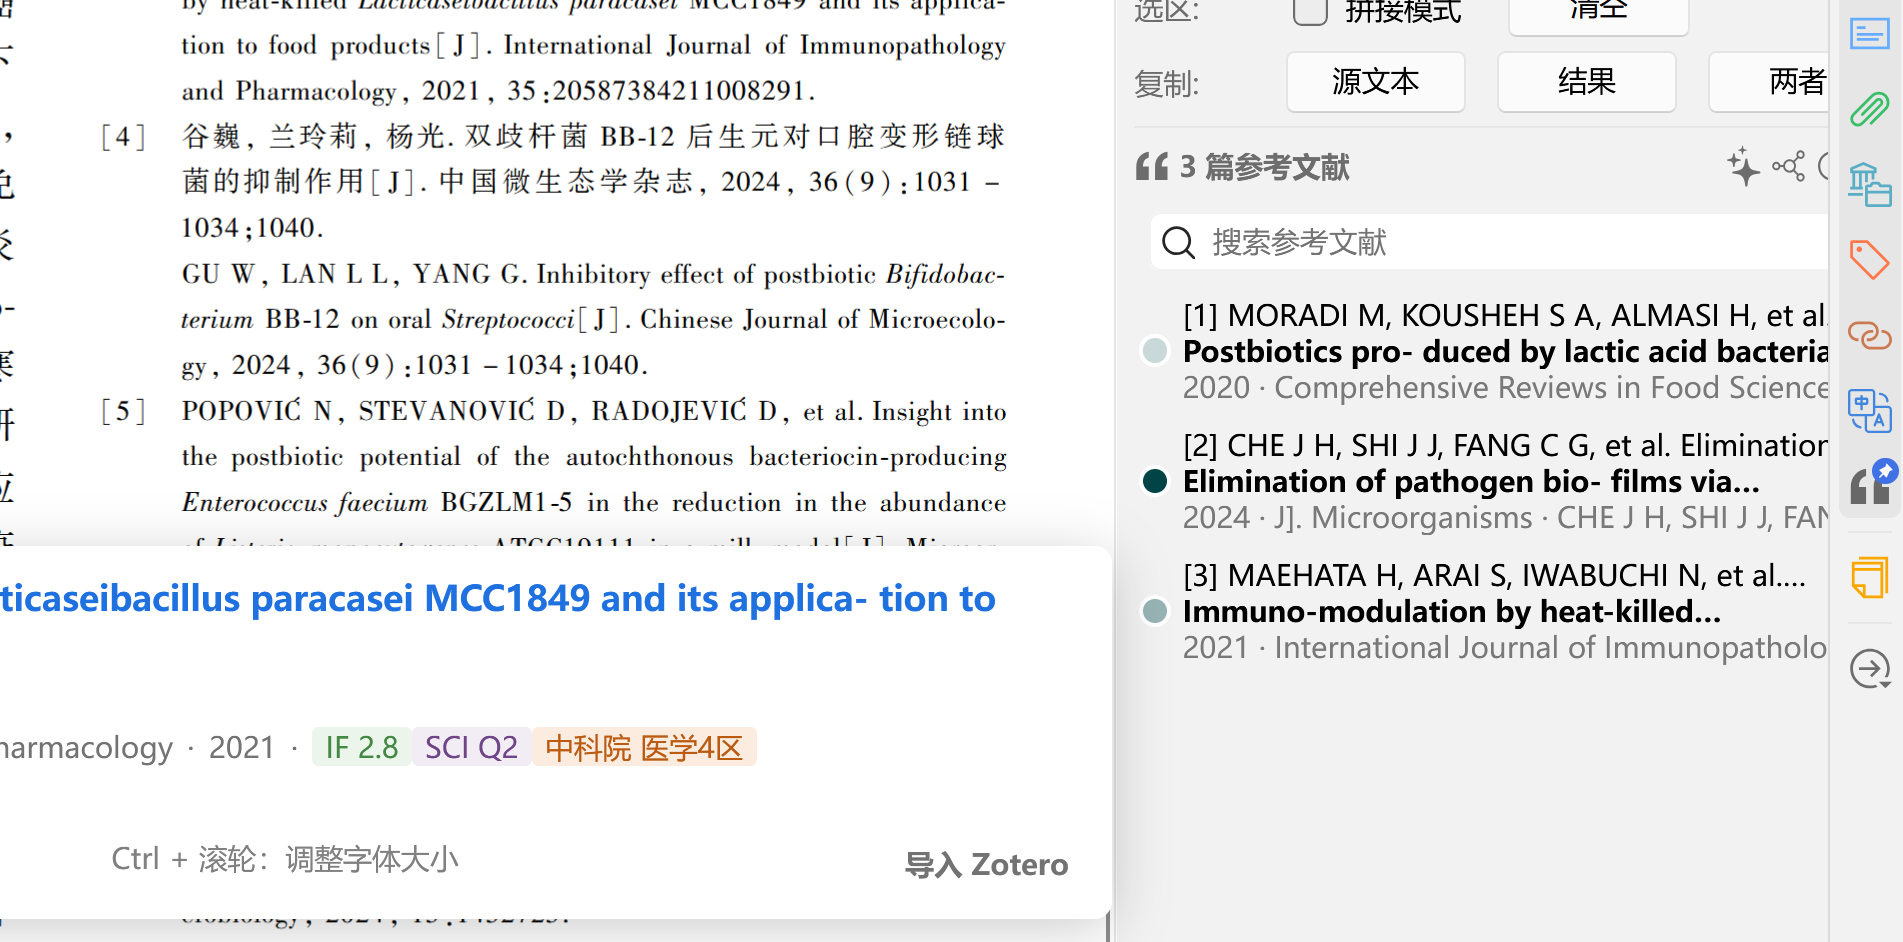
Why is it that when I scrape CNKI literature, the status shows normal, but when processing the references of this paper, only three references can be recognized? Is this because the fourth one is a Chinese literature that caused the process to get stuck? And why can't the system skip this problematic entry and continue to scrape the subsequent references?
https://s3.amazonaws.com/zotero.org/images/forums/u19918882/35fdihcd8ledlxkfcxpq.png
https://s3.amazonaws.com/zotero.org/images/forums/u19918882/ekzzizkvvsanl5ixhqil.png
https://s3.amazonaws.com/zotero.org/images/forums/u19918882/35fdihcd8ledlxkfcxpq.png
https://s3.amazonaws.com/zotero.org/images/forums/u19918882/ekzzizkvvsanl5ixhqil.png
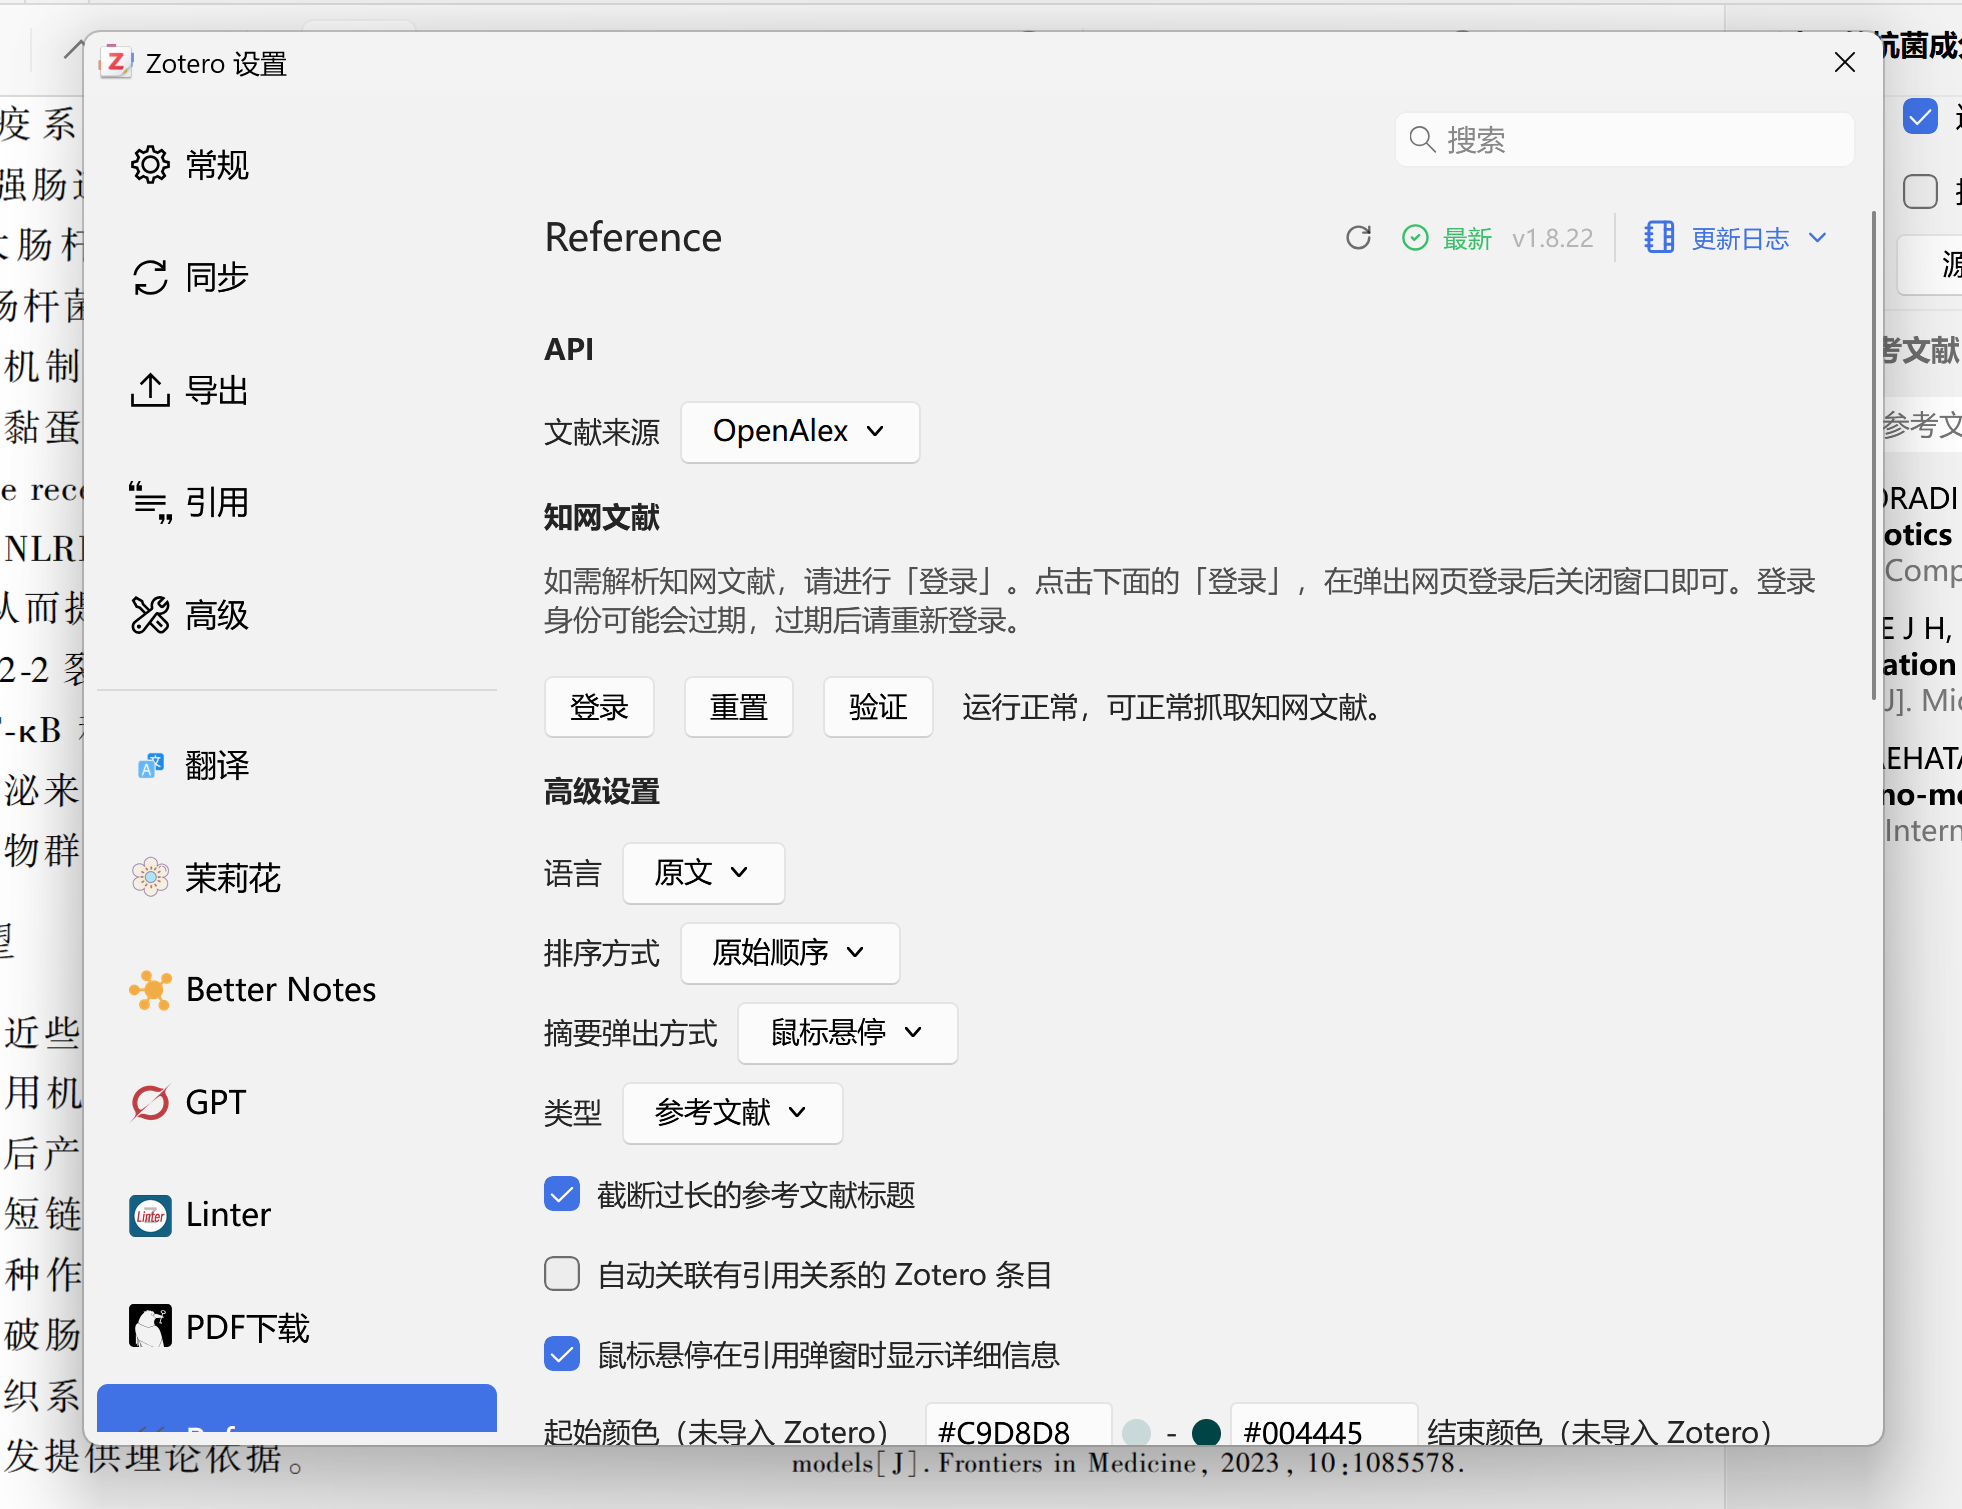
https://github.com/MuiseDestiny/zotero-reference
https://gitee.com/MuiseDestiny/plugins
While the plugin can use a number of different ways to populate the right-pane reference list (Open Alex, Semantic Scholar, parsing PDF text, CNKI for Chinese users), those sources are sometimes less than completely accurate.